B2B SaaS Keyword Research: Which Keywords Earn a Page
Founder, Grow Predictably · 15+ yrs building B2B revenue systems
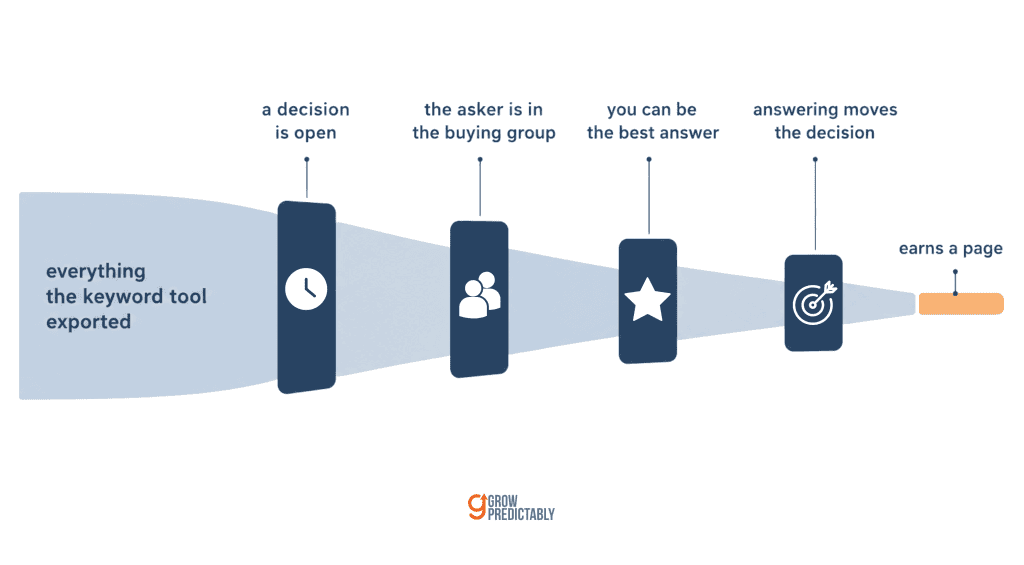
TL;DR: B2B SaaS keyword research fails at qualification, not discovery. A keyword earns a page when a real decision sits behind it, the person asking belongs to the buying group, you can be the best available answer, and answering moves the decision forward. Volume is the weakest of those four signals, because most of the market is not deciding today and the ones who are already carry a shortlist.
Key Takeaways
- A B2B SaaS keyword list does not fail because it is too short. It fails because nothing on it has been disqualified.
- Four tests decide whether a keyword earns a page: an open decision, an asker inside the buying group, a real chance of being the best answer, and forward movement on the decision.
- Volume estimates how often a term is searched. Difficulty estimates the ranking competition. Neither measures whether anyone is deciding anything.
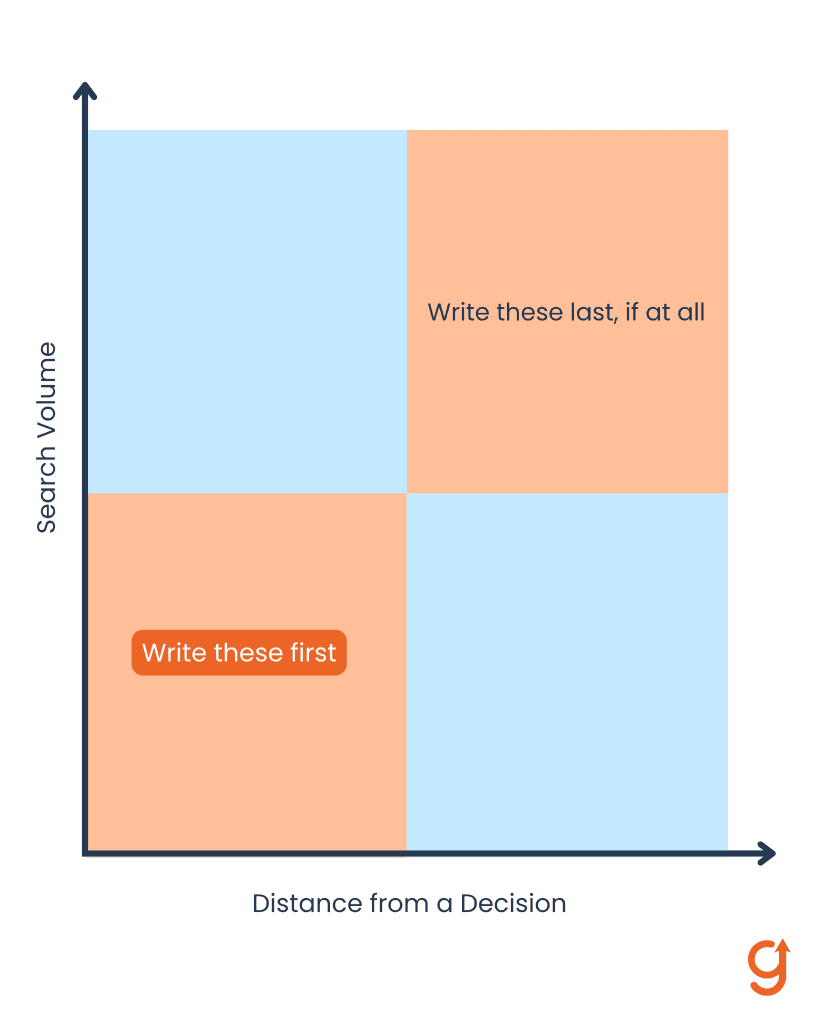
- Sequence what survives by how close it sits to a decision, not by how much traffic it promises.
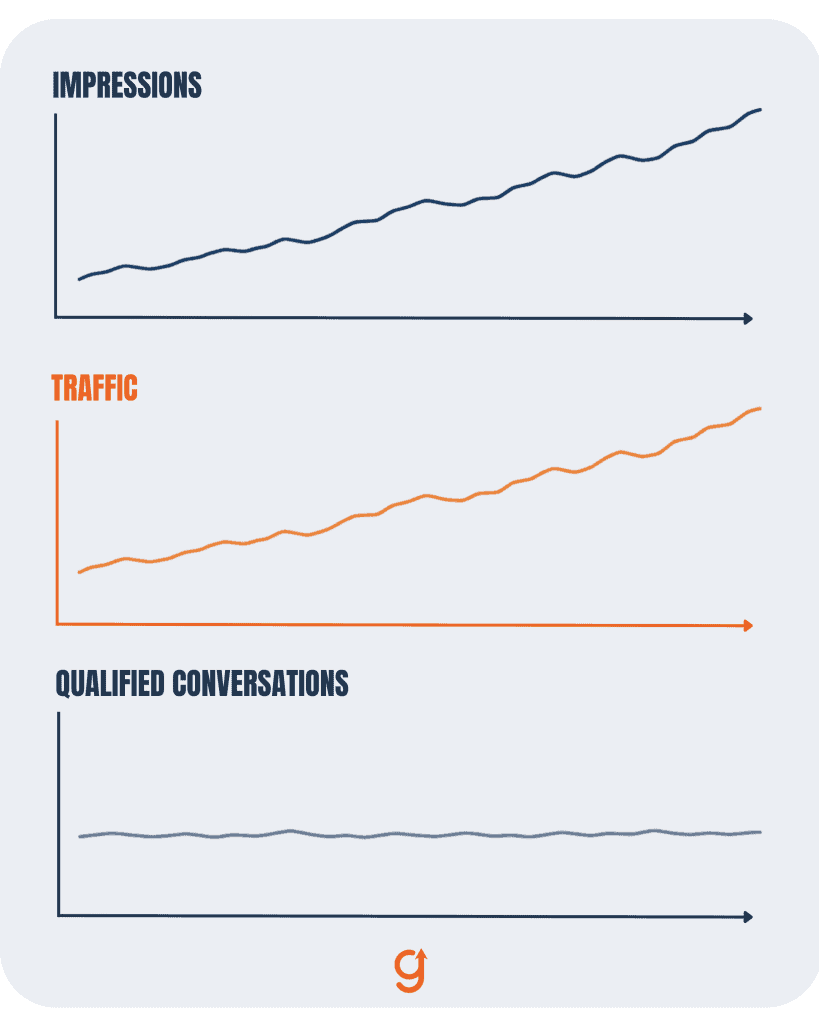
- Read impressions, traffic, and qualified conversations as three separate lines. A page can win the first two and still prove the keyword was wrong.
Keyword tools return B2B SaaS terms with volumes and difficulty scores attached, and they work exactly as advertised.
What the spreadsheet cannot tell a marketing leader is whether a buying decision sits behind a query, or whether that query is worth a writer’s week. That column does not exist.
This article is about the column the spreadsheet is missing.
Why does a keyword list full of traffic produce no pipeline?
Because the list was qualified on the wrong variable. Volume estimates how often a phrase is searched. Difficulty estimates the ranking competition. Neither one tells you whether a decision is open behind the query, so a list can be full of terms that rank, get read, and never touch a buying process.
The arithmetic underneath this is uncomfortable. Research from the Ehrenberg-Bass Institute puts the share of business buyers actively in the market at roughly five percent in a given quarter, with about 20 percent in market across a whole year.
“The 95% figure is not meant to be a precise rule. We’re using it as a heuristic to get the idea across that the vast majority of businesses, for a large proportion of products, are not in the market in particular time periods.”
John Dawes, Ehrenberg-Bass Institute
Take the heuristic rather than the decimal point. The implication for keyword selection is narrower: high volume can’t tell you whether anyone is actively deciding. A page can attract traffic without proving that a buying process exists behind it.
What actually makes a keyword worth writing for?
I run every keyword through four tests, in order. Each one is pass or fail, and failing even one is enough to drop the term. These tests are subtractive by design. A keyword tool export won’t tell you any of this, and that’s fine. Terms that fail the first test stop there, and that’s the tool doing its job, not falling short.
Test one: Is a decision open behind the query?
Someone typing this phrase is choosing between real options, and something happens depending on which way they go. “How does SSO work” is a learning question. “SSO requirements for enterprise procurement” is a decision question, because a procurement checklist is sitting on the other side of it. The phrasing looks similar. The intent isn’t.
Test two: Does the person asking sit in the buying group?
A B2B SaaS purchase is made by a group, not a person, and high search volume doesn’t establish buying authority. A student, a job seeker, or a practitioner three layers below the decision can be genuinely interested and still be structurally unable to buy.
If I can’t say which seat in the buying group is asking, I can’t say what the page is for. This comes down to knowing who the decision actually belongs to, which is its own piece of work, and it has to happen first.
Test three: Can you be the best available answer?
Not “can you rank.” Can you write the answer a reader would choose over everything else in front of them? If the current best answer is a vendor’s documentation, a regulator’s guidance, or a practitioner who’s done the thing a hundred times and you haven’t, the honest answer is no. Losing that test isn’t a failure. Writing the page anyway is.
Test four: Does answering it move the decision forward?
A page can be accurate, well matched to the buying group, and still leave the reader exactly where they started. The test is whether answering unblocks the next step or removes a reason to stall. That’s easier to judge once you know where the decision stalls in your own funnel, because the stall point is where an answer is worth the most.
Run the four tests against your list and keep only the terms that survive all four. A short list is the intended result, not a sign the tests are too strict.
How do you tell a buying question from a learning question?
The tell isn’t the funnel stage, and it isn’t the four-label intent taxonomy. The practical tell is whether a choice is being made, and whether the person asking carries any consequence for getting the answer wrong. Consequence is what separates curiosity from procurement, and it shows up in the phrasing.
Consider three pairs:
- “What is data residency” vs. “data residency requirements for EU customers”
- “Marketing automation examples” vs. “migrating from marketing automation to a customer data platform”
- “API rate limits explained” vs. “API rate limits for high volume integrations”
In each pair, the first phrase can be satisfied by any competent explainer. The second carries a constraint the asker must satisfy, which means someone will be held to the answer.
That’s the line. When a constraint appears in the query, I look for the rationale behind it.
Two cautions on applying this. A constraint in the phrasing is evidence, not proof, and some genuinely constrained queries belong to people who will never buy, which is exactly what test two is for. And the same phrase can sit on either side of the line depending on the market.
In a category where every buyer faces the same regulation, the regulatory query is a baseline requirement rather than a decision signal, because everyone is asking it and nobody is choosing based on the answer. Read the tell in the context of your own buyers, not as a rule about words.
Where do real buyer questions come from?
Not from a keyword tool, and that’s the objection worth meeting directly. A tool can tell you a phrase gets searched. It can’t tell you whether a decision sits behind it, who asked, or what happens next. The four tests need evidence the tool doesn’t have, and that evidence already exists inside the company.
I look in four places:
- Lost deal notes. These record the question that didn’t get answered well enough, which is the most valuable question in the building.
- Recorded discovery calls. These carry the exact words buyers use before anyone has taught them your vocabulary.
- Support tickets. These show what confuses people after they buy, and the same confusion can stop other people from buying at all.
- Sales objections. These are questions with consequences attached, by definition.
The wording matters as much as the topic. Keyword tools show search phrasing. Lost deal notes, recorded calls, and objections show the language around a live buying decision, and that difference is where most of the differentiated writing lives.
There’s a fifth source you already own and probably don’t read this way: the queries that already convert on your own site. Not the ones with the most impressions, but the ones that precede a demo request or a trial that turns into a conversation.
Expect that set to be small, oddly specific, and nothing like the head terms in the plan. It’s also the only evidence on this list that comes with the outcome already attached, which makes it the best starting point for pattern matching the rest.
None of these sources need a research project. One afternoon reading lost deal notes and last quarter’s converting queries will produce a better shortlist than another pass through a keyword tool.
Which qualified keywords should get written first?
I sequence by how close a term sits to a decision, not by how much traffic it promises. This runs against instinct, because the high-volume term looks like the bigger opportunity.
The reason sits in how B2B buying actually runs. In its 2025 Buyer Experience Report, drawn from more than 4,000 buyers, 6sense found that 94% of buying groups ranked preferred vendors before first contact. More pointedly, they ultimately purchased from that preliminary favorite 77% of the time. By the time a buyer talks to you, the shortlist mostly exists, and the front runner is usually going to win.
So the question worth owning is the one that gets you onto that list while it’s still forming. It’s the specific, constrained question a buyer asks while narrowing the field. Low volume close to a decision beats high volume far from one, because the first one reaches people who are actually choosing.
How do you know a keyword earned its page?
I read three lines separately: impressions, traffic, and qualified conversations.
Blended into one story about whether the page is working, they hide the disagreement between them. Kept apart, because each line can move without the others, the gaps between them are where to start looking. They narrow the question rather than answer it, since ranking, the search result itself, the offer, and the conversion path all sit between a keyword and a conversation.
I’ve watched those two top lines move at different rates. Inside a large B2B software company where I ran web optimization, the go-to-market pages grew organic impressions 14 percent year over year in the first half of 2025 and organic traffic 23 percent over the same period.
Traffic outran impressions, which is the good version of the split. The pages weren’t just being shown more; they were being chosen more often once shown.
The reverse pattern is the warning:
- Impressions climbing faster than traffic sends you to test three first, to check whether you’re surfacing for queries nobody wanted you for.
- Traffic climbing while conversations stay flat sends you to tests one and two, to check whether the people arriving are deciding anything and whether they sit in the buying group.
Neither gap proves the answer, but each one tells you which question to open first, so the quarter’s diagnosis starts somewhere specific.
A separate piece of work at the same company makes the point from the other end. After a site redesign I contributed to, average search ranking position improved 33 percent and marketable users from search rose 53 percent in the third quarter of 2024.
The ranking number is the vanity line, and the marketable users number is the real one. They moved together, which is the pattern worth wanting, though a redesign changes enough at once that no single cause can be read off two numbers.
Give it a quarter before reading any of this. Less than that and you’re reading noise.
What changes when your buyer asks an AI assistant?
The four tests hold, and test three gets sharper teeth. An assistant doesn’t hand back a list of pages. It answers, and it draws on whichever sources it treats as the best available answer. Being second best used to mean a lower position on a page the reader still scanned. Now it can mean not appearing at all.
That raises the cost of writing a page you can’t honestly win. It also raises the value of the constrained, specific question, which is the kind a generic explainer answers worst.
Google’s own guidance has pointed in the same direction for years, recommending a focus on people-first content over content made primarily to gain search engine rankings.
Whether your own pages get named in those answers is measurable rather than a matter of opinion, and choosing what to measure is the method for picking which buyer questions to measure rather than guessing at prompts.
Where should you start with your own keyword list?
Open the list you already have and run the four tests against it this week. Take them in order and stop at the first failure, rather than scoring every term against all four. Mark what fails test one and set it aside, so what you plan from is only what survived.
Scoring everything against everything turns a morning into a project, so stop early. Resist the urge to argue with the result too: a list that survives intact is a sign the tests were applied gently, not that the list was good.
What is left is your actual content plan. It will be shorter, more specific, and less comfortable to present than the plan you had, and it will be the first version of that plan aimed at people who are deciding something.
If you want the same diagnosis run across the whole funnel rather than the keyword list, take the Growth Gap Scan.
Frequently Asked Questions
How many keywords should a B2B SaaS company actually target?
Fewer than the list suggests. The number that matters is not how many terms you found but how many survive the four tests, and on most lists that is a small fraction. A plan built on 15 qualified terms will usually outproduce one built on 200 unqualified ones, because every page is aimed at someone who is actually deciding something.
Is keyword search volume useless in B2B SaaS?
No, but it is a tiebreaker rather than a qualifier. Volume tells you how many people type a phrase. It never tells you whether a decision sits behind it or whether the person asking can buy. Use it to choose between two terms that have already passed the four tests, never to decide which terms are worth testing.
How do you find buyer questions if you have very little search data?
From conversations rather than tools. Lost deal notes, recorded discovery calls, support tickets, and sales objections all carry the exact wording buyers use before anyone teaches them your vocabulary. A company with almost no search data usually has months of this material sitting unread, and it is better evidence than a keyword export because the outcome is already attached.
Should you target competitor comparison keywords?
Only when a decision is genuinely open, and you can honestly be the best available answer. Comparison queries pass the first test easily, because someone choosing between named options is deciding. They fail the third test often, and a comparison page you cannot win honestly hands the reader to the competitor you just named for them.
How long before a new page shows whether the keyword was worth it?
Give it a quarter, then read three lines separately rather than one. Impressions, traffic and qualified conversations can move independently, and the pattern between them tells you which test you got wrong. Reading them sooner than a quarter, or collapsing them into a single story about whether the page is working, produces noise rather than a signal.
Does keyword research still matter when buyers ask AI assistants?
Yes, and the qualification step matters more. An assistant answers the question instead of listing pages, so being second best often means not appearing at all rather than appearing lower. That raises the cost of writing a page you cannot win and raises the value of the specific, constrained questions assistants have the least good material to answer from.
About the author
Brian helps B2B founders install marketing + automation engines powered by Co-Thinking with AI. With 15+ years building predictable revenue systems, he's worked with SaaS, agency, and service businesses on 90-day done-with-you growth accelerators.
Ready to see your real growth gap?
Two minutes in the Growth Gap Scan and you walk away knowing the one thing capping your pipeline. Free, no obligation.