How to Tell Whether AI Assistants Name Your B2B SaaS Company (and What to Do When They Do Not)
Founder, Grow Predictably · 15+ yrs building B2B revenue systems
By Brian Shelton, Founder of GrowPredictably.com
TL;DR: You cannot manage what you have not measured, and almost nobody is measuring AI visibility correctly, because the obvious metric does not exist. There is no stable ranking position inside a generated answer. What you can measure is how often you get named across a fixed set of buyer questions, asked repeatedly, on more than one engine.
Key Takeaways
- Generated answers have no stable ranking position. Research from SparkToro found there is under a 1 in 100 chance that two runs of the same question return the same list of brands.
- What is stable enough to manage is frequency: how often you appear across many runs of the same fixed questions.
- The instrument comes before the tactics. A question set you agreed in advance and never edit is what makes a later measurement comparable.
- Some of what decides the answer is not on your website at all, which is why an on-site-only program can plateau.
- None of this requires replacing your SEO agency, and in most cases it should not.
Why can your search dashboard look healthy while AI recommends a competitor?
Because they measure different surfaces. Your SEO reporting watches ranked links and the clicks they produce. An assistant composing a shortlist draws on what it can retrieve about you, from your site and from sources you do not control. Nothing in a rankings report looks there, so the gap stays invisible until a buyer mentions it.
This is close to the default state rather than an unlucky edge case. The 2X AI Visibility Index, reported by Demand Gen Report, analyzed 70 B2B companies and found 96% of them invisible in AI-driven buyer discovery, showing up only in late-stage queries where the buyer already knew the company name.
The surrounding shift is not subtle either. Pew Research found that users who met an AI summary clicked a traditional search result in 8% of visits, against 15% for those who did not, and SparkToro puts 68% of US Google searches ending without a click in early 2026, up from about 60% in 2024.
Why is there no such thing as a ranking position in AI?
Because the answer is generated fresh each time, and it is far less stable than a search results page. Ask the same question twice and you can get two different lists of companies in two different orders. A tool selling you a single “position” inside that is reporting noise as a measurement, and optimizing against it means chasing variance.
This is measured, not assumed. SparkToro published a study in which 600 volunteers put 12 prompts through ChatGPT, Claude, and Google AI a combined 2,961 times across November and December 2025.
Rand Fishkin, co-founder and CEO of SparkToro and the study’s author, states the implication plainly:
But, any tool that gives a ‘ranking position in AI’ is full of baloney.
The underlying number is the striking part. The research found there is under a 1 in 100 chance that ChatGPT or Google’s AI, asked the same thing 100 times, returns the same list of brands in any two responses. Ordering is worse still.

But the same study points at what does hold up. Fishkin’s own conclusion is that “visibility % across dozens to hundreds of prompts run multiple times is a reasonable metric.” Position is noise. Frequency across repetition is signal. That single distinction is what separates a measurement program from a dashboard that makes you feel busy.
It also gives you a fast way to screen vendors. Ask what their number means. If the answer is a rank, or a composite score with no visible questions behind it, you now know what you are looking at.
What should you measure instead?
A fixed set of the questions your buyers actually ask, agreed before any work starts and never edited afterwards. That last part carries most of the weight. A question set you revise between measurements cannot be compared against itself, so the moment you change it, you have destroyed your own ability to tell whether anything improved.
Build it from real buying language, not category terms. The questions worth freezing sound like a buyer talking to an assistant, not like keywords:
- Who are the best vendors for this specific problem in this specific industry?
- Which one works alongside tooling we already have?
- Which one is credible for a company our size?
- What are the alternatives to the vendor we are currently considering?
Up to 20 is usually enough to be meaningful without becoming a project, and that number is a ceiling rather than a target. Build the set to the strongest questions your market supports instead of padding it to reach a count. Write them down, get them approved, and then leave them alone.
The difference between a useful question and a useless one is whether a real buyer would type it. “Best B2B SaaS marketing platform” is a keyword wearing a question mark, and the answer will be dominated by whoever has the most category coverage.
“Which customer onboarding tool works for a 40-person SaaS company already using HubSpot” is how someone actually asks, and the answer set is narrower, more competitive, and far more likely to contain the buyer who becomes your pipeline.
Be careful about flattering questions too. A set built around terms you already own will show healthy numbers and teach you nothing. The questions worth freezing are the ones you are afraid to ask, because those are the answers a buyer is getting whether you measure them or not.
Run each one more than once, because a single run tells you very little. Run them across ChatGPT, Claude, Perplexity and Google AI Mode, because retrievability is per-engine and the same company routinely appears on some and not others.
What does a day-one baseline actually record?
Four things, and the last two are the ones teams forget. Where you appear. Where you do not. Which competitors are named in the answers where you are absent. And which sources the engine drew on to build the answer, because that tells you where the influence actually sits.
That fourth item is what turns a score into a plan. When you can see that an answer was assembled from three third-party pages and none of them are yours, you no longer need to guess what to work on.
Record it so it can be repeated exactly. That means the questions verbatim, the engines used, the date, and the raw answers kept rather than summarized. If you cannot rerun it identically in 30 days, it was not a baseline, it was a snapshot.
A worked example from a different domain makes the discipline concrete. Before switching this site to a new front end, I warmed all 375 sitemap URLs against the preview before the DNS change. 369 returned 200 and one returned an expected 301.
Five failed persistently while still returning 200 on the live site, so launching would have regressed them: two server render crashes and three re-slugged pages. The live site looked completely healthy. Only measuring against the thing I was about to change surfaced the failures, and the same logic applies here.
Why is some of what decides the answer not on your site?
Because engines assemble answers from whatever they can retrieve, and a lot of that sits on domains you do not own. Comparison articles, roundups, review sites, community threads, and industry publications all feed the shortlist.
A company can have an excellent website and still lose the answer to a listicle it is missing from.

This is the part an on-site-only program cannot reach, and it explains a common plateau: the site work gets done, the pages improve, and the answers barely move, because the sources feeding those answers were never touched.
The honest framing is that this is a different kind of work with a different tempo. Getting a factual correction made on a third-party page, or becoming genuinely worth including in a comparison, depends on other people’s editorial decisions.
It is slower, it is not guaranteed, and any vendor promising placements should be treated with suspicion.
Can you do this without replacing your SEO agency?
Yes, and in most cases you should not replace them. This work sits beside a search program rather than on top of it. Crawlability, indexing, page speed, and current comparison and product pages are all upstream of every AI outcome discussed here, and those are exactly the things a competent SEO team is already maintaining.
What you are adding is a measurement surface the SEO program was never designed to cover, plus the specific page and off-site work that surface points at. That is a scoped addition, not a rebuild, and it does not require moving your site, changing your CMS, or handing anyone else the keys.
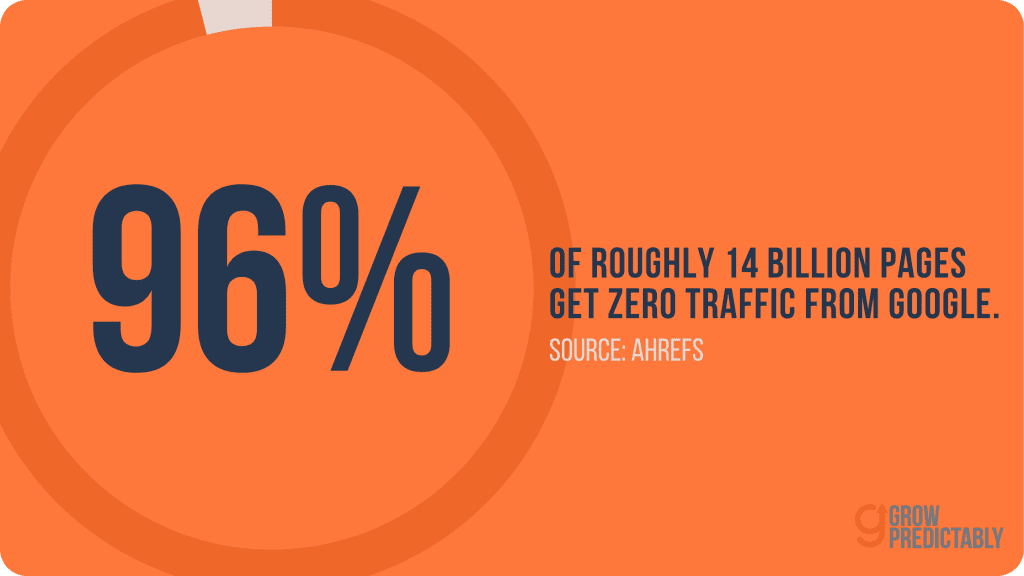
It is worth being clear about what the search program is already protecting you from. Ahrefs studied roughly 14 billion pages and found 96.55% of them get zero traffic from Google. Publishing volume was a weak strategy before answer engines arrived, and it is no better now. The foundations a competent SEO team maintains are what keep your pages retrievable at all.
The friction usually shows up somewhere else: whether anyone internally can approve and publish page changes on a reasonable timeline. If that person does not exist, no measurement program will help, because the findings will sit in a document.
What should you have after 90 days?
A baseline, three comparable reruns, and a clear read on direction. Not a promise about model behavior, which nobody can honestly make, but a defensible answer to whether your presence in the answers that shape your shortlist is moving, holding, or slipping, measured against questions you approved on day one.
You should also own the instrument. The question set, the raw answers, and the record of what changed between runs should be yours to rerun without anyone’s help. If a measurement program leaves you dependent on the vendor to know whether it worked, it has failed at the thing that mattered most.
And you should expect an honest report of non-movement where it happened. Engines update on their own schedules, answers vary run to run, and 90 days is not long. A report that shows improvement everywhere is less credible than one that shows where the work landed and where it did not.
Be equally careful about the opposite error. If presence improves, resist the urge to attribute it cleanly to one intervention. Several things move at once during a 90-day program, and engines change independently of anything you did.
The defensible claim is that presence moved on a frozen question set over a known period, with a record of what was changed in between. That is weaker than a causal story and considerably more honest, and any vendor offering you the stronger version is telling you something the data cannot support.
If AI visibility is the constraint you need to test, the AI Search Assessment is where this gets done properly: up to 20 buyer questions you approve before anything runs, checked across ChatGPT, Claude, Perplexity and Google AI Mode, with every raw answer kept so you can rerun the same set yourself next quarter.
Frequently Asked Questions
How do you measure AI visibility if there are no rankings?
You measure frequency instead of position. Take a fixed set of buyer questions, run each one several times across more than one engine, and record how often your company is named and who is named instead. Position inside a generated answer is unstable enough to be meaningless, but appearance rate across repeated runs is consistent enough to manage.
What is a frozen question set?
It is the list of buyer questions you agree before any measurement, and then never change. Freezing matters because comparability is the whole point. If the questions shift between your baseline and your later measurements, you cannot tell whether a difference reflects real change or just a different question, so the measurement stops meaning anything.
Can you improve AI visibility without replacing our SEO agency?
Yes. This work sits alongside a search program rather than replacing it, and the technical foundations your SEO team maintains are upstream of every AI outcome. What gets added is a measurement surface plus the page and off-site work it points to. Replacing a functioning SEO program to fund this is usually a mistake.
Does this work the same on ChatGPT and Google?
No, and that is why more than one engine belongs in the measurement. Retrievability is per-engine. The same company is regularly named by one and missed by another, and each builds its answers from different kinds of sources, so a single-engine measurement will give you a confident but incomplete picture. A serious check covers ChatGPT, Claude, Perplexity and Google AI Mode.
How long before anything moves?
Longer than a ranking change, and less predictably. Engines refresh on their own schedules, and answers vary between identical runs, so no single check tells you much. Read direction across a full question set over 30 to 90 days, and treat any single answer, good or bad, as one observation rather than a result.
What if an answer cites a source that is not our site?
That is common and it is useful information rather than a dead end. It tells you the influence sits on a third-party page. The options are to earn a place in that source, to correct it where it states something verifiably wrong about you, or to strengthen your own material enough to be retrieved alongside it.
About the author
Brian helps B2B founders install marketing + automation engines powered by Co-Thinking with AI. With 15+ years building predictable revenue systems, he's worked with SaaS, agency, and service businesses on 90-day done-with-you growth accelerators.
Ready to see your real growth gap?
Two minutes in the Growth Gap Scan and you walk away knowing the one thing capping your pipeline. Free, no obligation.